Let’s continue with the “building in the public” concept. First, thank you for being here and for your patience as I share my experiences and muddle through half-formed thoughts.
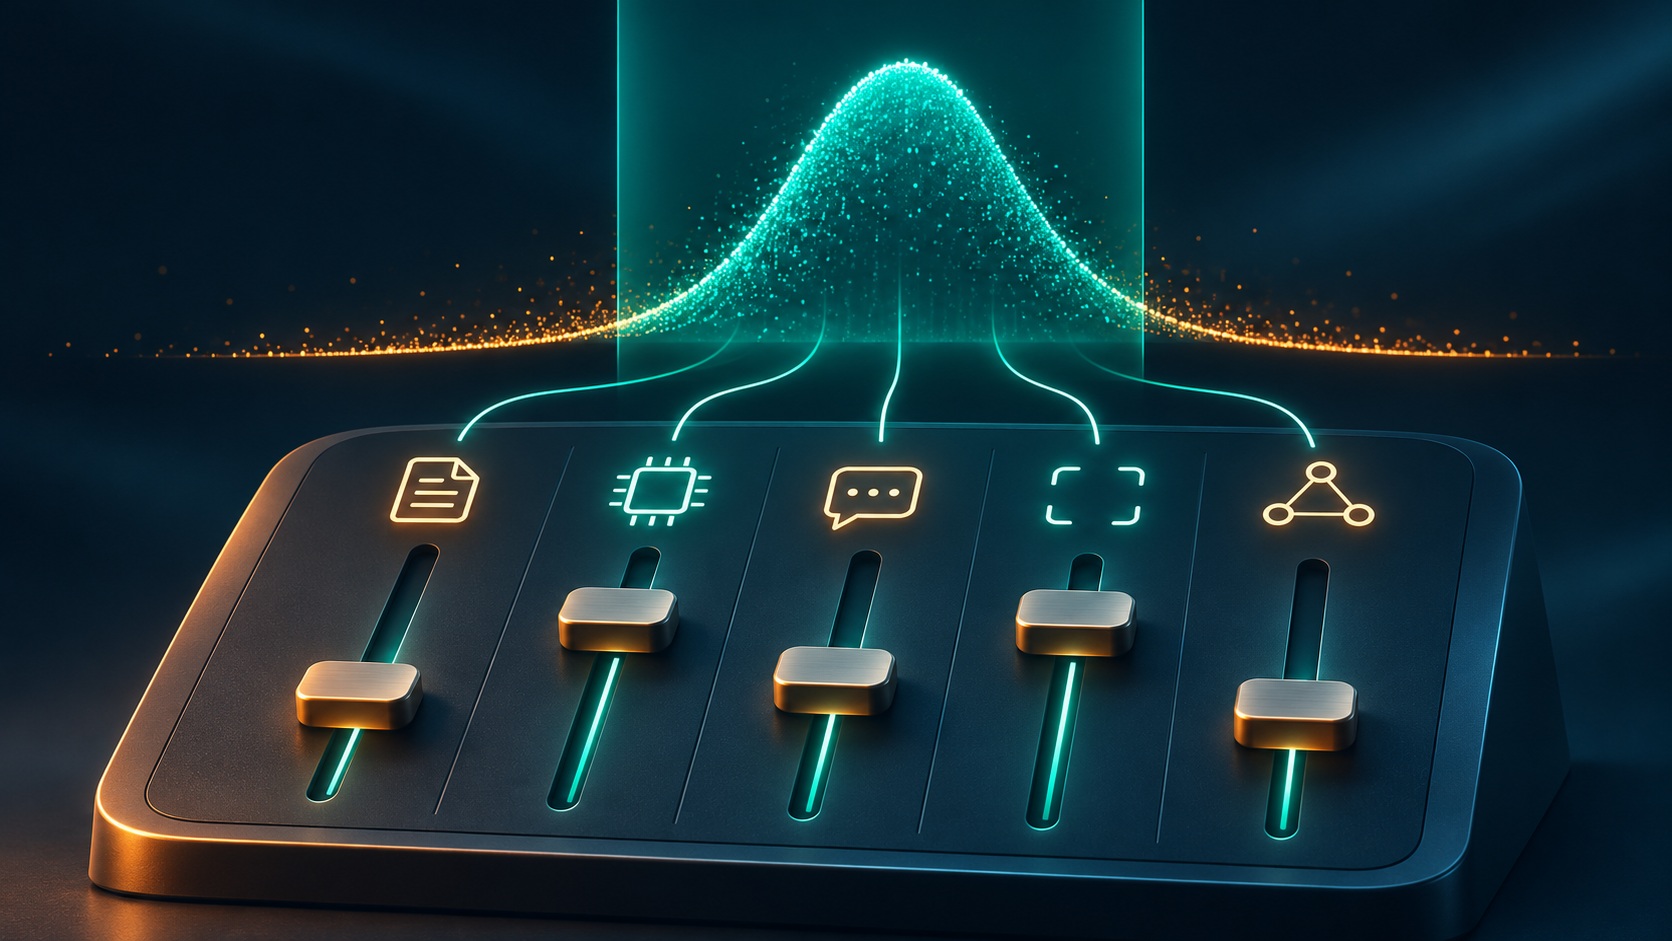
In the last article, I argued that agent engineering isn’t about getting the best possible output once. It’s about shaping the output distribution so more of it lands within your organization’s acceptable operating range by raising the average, reducing variability, and catching what’s left.
Today I want to get practical: the five levers I actually pull to do that. Fair warning, this is building in public. There’s no book on this yet, and some of my approach may turn out to be “less-correct.”
I see it this way, and these are by no means independent. Each impacts the overall performance.
- The agent prompt
- The model
- The request prompt
- Clean Context with no history
- The multi-agentic system
The Agent Prompt
Of all five levers, the agent prompt has had the biggest impact for me. A well-formed prompt raises the average quality of the agent’s output and narrows the spread, so more of what it produces lands inside the acceptable operating range. A poorly formed prompt does the opposite, and it can create what I call agentic cognitive dissonance (more on that below).
Prompt Template
I recommend building your agents from a prompt template. It makes each agent easier to maintain and the fleet more predictable, because every agent is built the same way. Don’t be married to your template, though. Update it as you find ideas that work better.
Vibe-coding a single agent might be fine. For a fleet, I don’t recommend it. When I started, my first few agents worked well, but the later ones performed noticeably worse. Without a template, each new agent drifted a little further from the last.
A template can be as simple as a fixed set of sections, in a fixed order:
Role → Mission → Authority → Knowledge → Tools → Validation → Guardrails
Orthogonality, Linkage and Consistency
I don’t believe any single template is best for everyone. I’ve seen agents run well on very different formats. The good ones share three properties: orthogonality, linkage, and consistency.
Orthogonality means each section covers one area and only that area. Authority defines what the agent can do. Knowledge defines what the agent knows and doesn’t know. A sales agent might be authorized to send sales emails (Authority) and know the SPIN and Challenger sales methods but not PAS (Knowledge). Tools, Validation and Guardrails each get their own section in the same way. The test: if a sentence could belong in two sections, it isn’t in the right one yet. This sounds straightforward, but it’s trickier than you’d expect.
Linkage means each section builds on the one before it. If Role comes first and Mission comes second, the mission should follow naturally from the role. Reading the prompt top to bottom should feel like one connected description of a single agent, not a stack of separate rules.
Consistency means the sections never contradict each other. Terms mean the same thing everywhere, and nothing in one section undermines another. When consistency breaks down, you get dissonance.
Agentic Cognitive Dissonance
In humans, cognitive dissonance is the discomfort we feel when we hold two conflicting beliefs at the same time. LLMs don’t feel discomfort, but I’ve seen something similar happen when an agent’s prompt sends mixed signals.
Say you define a Sales Agent, then list creating marketing graphics among its responsibilities. Nothing breaks. The agent doesn’t complain or throw an error. But every time it receives a task, it has to silently decide which agent it is: one that manages sales conversations, or one that produces marketing assets.
Sometimes it guesses one way, sometimes the other, and sometimes it blends the two. Each outcome might look reasonable on its own, but together they widen the distribution. That’s the variability we’re trying to eliminate, and it pushes more outputs outside the acceptable operating range.
The fix is usually structural rather than clever wording: give the agent one coherent identity, and move the conflicting responsibility to a different agent.
The Model
The model selected has a tremendous impact. Larger frontier models are excellent, especially for goal-based agents, but their costs for an ongoing agentic team can be astronomical. I typically look for low-cost, older models. What is the smallest, cheapest model that I can use with this agent?
Model selection is a personal preference. Because of the testing required, especially during development, I recommend picking one model and sticking with it until you have a reason to change.
Request Prompt
The request you give an agent greatly affects its performance. LLMs are notorious for reading between the lines and assuming understanding. For example, asking a strategy agent, “Should I expand to a new location?” assumes expansion is the only option available and the next logical step. You risk the LLM “leaning” into this assumption.
I recommend using structured JSON where possible. This gives the agent the information it needs in an easy-to-parse format. Use free text with strategic or managerial agents, including goal-based agents.
You’ll likely spend more time than you imagined getting the inter-agent prompting to the level you need for stronger results. But a strong, consistent request prompt can move the agent’s behaviour firmly into the acceptable range.
Clean Context Window & No History
Alright, here is where I will surely get some pushback, and probably rightly so. One of the most attractive features is the LLM’s ability to “learn” what you prefer and what your business is about. Who among us hasn’t been amazed by the LLM pulling information from a previous discussion and referencing it in the current thread?
Certainly, for assistant-based agents, this can be an attractive feature. I do, however, feel that it comes with some hidden risk. The LLM will start to converge on only what you want to see and what you previously responded to positively. A future article will discuss this in more detail.
For LLM-based agents, history introduces greater risk primarily because it can cause the agent to behave differently from the tested and approved version. If history affects the agent’s decision-making, you will lose agent reliability, and agent behaviour may drift over time.
For this reason, I prefer a clean contact window with no ability to view previous conversations and no history of previous interactions or discussions. If history is truly required, I recommend building solutions where you control what history the agent can access.
Multi-Agentic Systems
With multi-agentic systems, information, requests, and results get passed among agents. At each handoff, the agent can review the request, determine whether it is in scope, and identify any missing information. This ensures each agent receives the information they need and reduces the risk of cascade failure, where a small error is amplified as it passes through an agentic team.
Within the multi-agent system, specific quality and control agents can review progress and identify problems early, allowing the team to self-correct. If an agent’s output falls outside the acceptable band, the quality and control agents can pass the information back to the agent for rework.
In the end, this increases the likelihood that the final output falls within the acceptable zone.
One note on multi-agentic systems and model selection. I have found that using multiple models across the agentic ecosystem yields better overall results. My instinct is that the agent system leverages each model’s strengths.
Wrapping Up
None of these levers work alone. A strong agent prompt can’t fully make up for a model that’s too small for the job. A clean context window won’t help if the request prompt leads the agent toward the wrong answer. And a multi-agent system can’t fix agents that were unreliable to begin with. Each one shapes the distribution, and together they decide how much of it lands inside the acceptable operating range.
I don’t think there’s a single right way to do any of this yet. This is what has worked for me so far, and I expect some of it to change as I learn more, which is the point of building in public.