LLMs Amplify our Cognitive Biases
Because LLM responses are fluent, confident, personalized and well structured, they can make an idea feel more accurate or well supported than it really is.
The risk is not simply that the AI may be wrong, but this interacts with our human biases making us less likely to notice weak assumptions, missing information or alternative explanations.
Confrimation Bias
We favour information that supports what we already believe.
When a question contains an assumption, an LLM can build a remarkably persuasive case. The danger is a well-written answer can feel like independent validation when the model may simply be reasoning within the frame we gave it
Authority Bias
We give more weight to information when it appears to come from an authoritative source.
LLMs communicate with a tone, confidence, structure and specificity that we associate with experts. They may incorporate our company, industry, and data making the advice feel like it comes from an expert who deeply understands our business.
But authoritative presentation is not the same as authoritative knowledge.
Forer Effect
Generic observations feel highly personal when we recognize ourselves in them.
LLMs can take broadly applicable advice (“focus on your strongest customers”) and surround it with details to feel highly customized. Personalization can make generic advice feel like unique insight.
WYSIATI
What You See Is All There Is
We naturally create coherent stories from the information available and often fail to notice what is missing. LLMs amplify this because they produce complete, polished narratives with few visible gaps.
It is more important to ask: what information is missing? What assumptions were made? What alternatives were never considered?
Agent Engineering: From Capability to Reliability
Getting an AI agent to produce a good result once is relatively easy. Getting it to produce consistently acceptable results is the real engineering challenge.
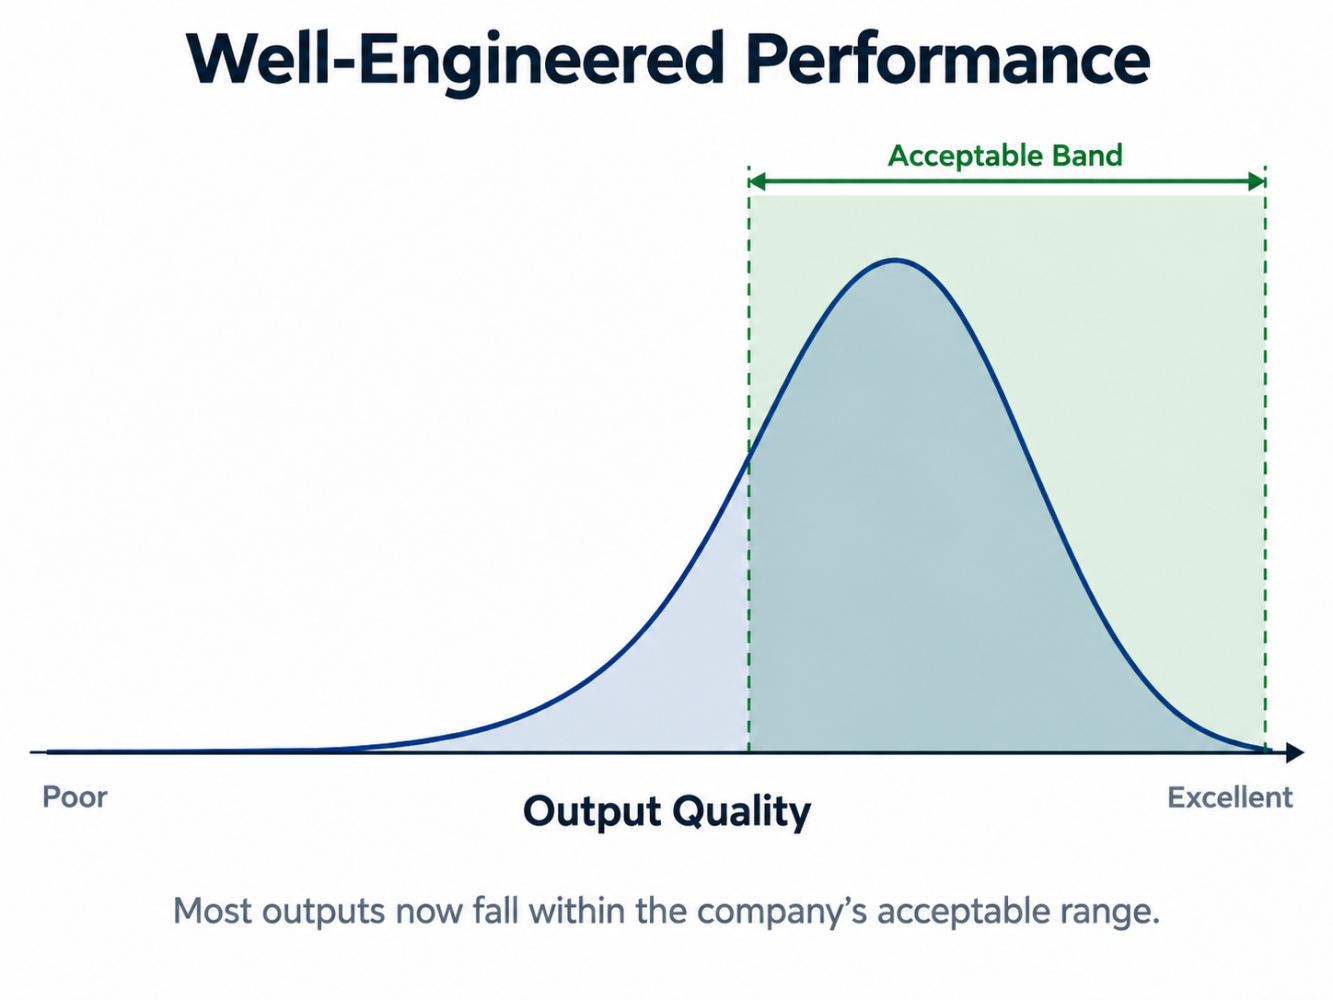
Unlike traditional software, LLM -based agents produce variable outcomes. Some results are excellent, others are unacceptable, and many fall somewhere in between.
The goal of agent engineering is to shift the distribution of outcomes toward the acceptable performance zone, increasing the proportion of results that meet business requirements while reducing variability and failures.
This is achieved through better prompts, model selection, context management, workflow design and quality controls.
The Lesson: Don’t judge an agent by its best output. Judge it by how consistently it delivers results within the acceptable zone.
Slow Down LLM Thinking
LLMs give you finished answers quickly. The output looks complete, but the reasoning behind it may have been rushed.
A model performs better when it has one area of the full problem to manage.
We use this principle when we build agents and agentic workflows.
As an example, we use four agents when building a new agent.
How We Build Agents One Step at a Time
Business Case
Why does this agent exist, and what will it change? How does it fit within our current system?
Technical Specification
With the business need understood, this agent works with me to determine the technical needs, risks, and capabilities of the new agent.
Prompt Engineer
The prompt engineer agent uses the technical specification and the business case to write an agent according to our prompt template and guidelines.
Agent Reviewer
The Agent Reviewer works with me to review, understand, score and update the new agent section by section. This helps me fully understand how the agent works and to mitigate risks and bugs.